From code storage to code discovery
TL;DR: Git gave code its write side. Agents need a read side: a materialized, intent-indexed catalog of verified capabilities. When machines produce code, software development becomes manufacturing, and manufacturing runs on catalogs and metrology.
MCP (Model Context Protocol) may be the beginning of a broader shift: software and its APIs need to become need to become queryable by AI agents, with minimal time and tokens spent finding and evaluating a capability before calling it
Indexes, not scans
This looks surprisingly like a database problem. A database doesn’t scan every record; it uses indexes to go straight to the data.
Agents mostly scan, and inside a repository that works well. Identifiers are precise keys, grep is fast, and nothing goes stale. Databases are similar: on a small table, the query planner picks a full scan because it is cheaper.
The plan changes across an API boundary. An SDK consumer often has no source to scan, and the knowledge it needs most (what to avoid, which default applies, what comes next) is often not in code at all. Thousands of consumers also pay for the same exploration again. Many reads, few writes: the classic case for an index.
If MCP starts to address this for applications, what is the equivalent for libraries and SDKs?
The missing read side
We already have one half of a database for code. Version control systems like Git are the write side: the source of truth that preserves history, integrity and distributed changes. But Git is optimized for writing and storing code, less for finding and using it.
Software architecture has a name for this split. CQRS (Command Query Responsibility Segregation) separates the write model, built for consistent changes and transactions, from the read model, built for fast queries. For code, the read side exists only in fragments: code indexes like Sourcegraph’s SCIP, Aider’s repo map, generated wikis like DeepWiki, documentation servers like Context7, llms.txt and AGENTS.md. Most of them are organized by code structure or by page, not by intent. Each solves part of the problem, and their growing number shows the need is real. What’s missing is a common model: a standard read model for agents.
The closest thing we have to a read side today is documentation, but it is built like a write model. Reference docs are essentially normalized: each fact lives in one place, organized by code structure and connected by cross-references. That works well for humans learning a system.
For an agent solving a task, it means expensive joins: the method on one page, the parameter type on another, the coordinate system somewhere else. Every join costs tokens and time.
Samples are the exception. A good sample is already denormalized, built around a task, with everything needed in one place. But samples usually cover only the happy path of the most common tasks. The long tail of the API, where an agent needs help most, is left to the reference docs.
So reference docs have the coverage but the wrong shape, and samples have the right shape but not the coverage. An agent-facing read model needs both: denormalized like a sample, organized by intent rather than by class hierarchy, and as complete as a reference.
A single entry might look like this:
intent       geocode parcel
description  returns the cadastral parcel containing a point
call         parcels.queryAt(lon, lat, crs)
verified     test_parcels_query_at · commit a1b2c3d · 2026-09-28
tolerance    exact point-in-polygon; p95 < 40 ms; CRS: EPSG:4326, EPSG:5514
fails when   point on a shared boundary → returns first match only
crs          default EPSG:4326, degrees
One open question is who owns the vocabulary. An agent may ask for “point in parcel” when the entry says “geocode parcel”. The vocabulary could come from the library author, from a domain standard (for geospatial, OGC already names many spatial operations), or be learned from what agents actually ask for. Either way, intent isn’t an exact key, so this part of the read model behaves more like a search engine than a B-tree.
Materialized views
Denormalized data drifts. Databases fix this with materialized views, derived from the source and refreshed as it changes.
The agent layer should work the same way: generated from signatures, samples, docs and tests. An entry whose test fails goes stale. Entries can also grow from use: a successful agent scan becomes a candidate, kept only if it passes a test.
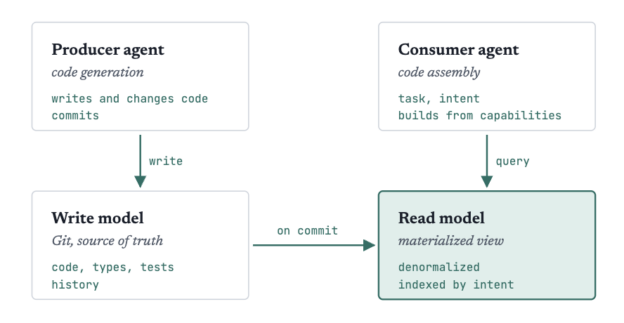
Producers write into the write model; consumers query the read model. Each role needs a different structure.
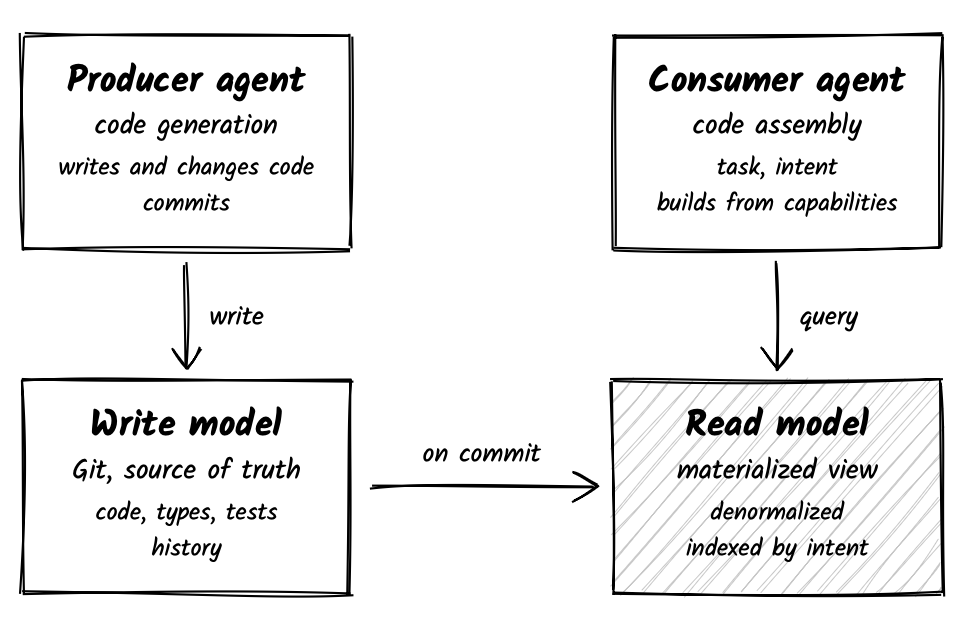
Figure 1: Two roles, two models. The same agent can play both.
From software development to “Software Manufacturing Intelligence”
Engineers select parts from catalogs with precise specifications: dimensions, tolerances, materials. A capability read model is that catalog for software.
A catalog is only as good as its measurements. A part’s datasheet doesn’t describe what the part is meant to do; it states what it was measured to do (load, tolerance, operating range) and under which standard. A capability entry needs the same evidence: the test that proves the call works, the commit at which it last passed, the tolerances it holds (accuracy, latency, supported inputs), and the known ways it fails.
This is the metrology of software manufacturing. Producer agents can generate entries cheaply; what makes them trustworthy is that each one is measured, and re-measured on every commit.
A software factory might be very similar to a physical one. Before anything is manufactured, someone has to find out how. That happens in an R&D prototype workshop: the problem is explored, several hypotheses are tested in parallel as cheap prototypes, and a diagnostic loop refines them until one path is proven. Then operational software manufacturing actually starts.
Takeaway
In the workshop, agents scan, write and test. They are producers, and the write model serves them well. In manufacturing, agents assemble proven parts. They are consumers, and they need a catalog: what each part does, where it fits, when not to use it, and evidence that it still works. Today every agent rebuilds that catalog from scratch, for every task.
R&D explores, manufacturing assembles, metrology makes the assembly trustworthy. Git gave code its write model. Agents now need the read side.